 クリック」
 弊社は製品に自信を持っており、面倒な製品を提供していません。


割引はありますか?
我々社は顧客にいくつかの割引を提供します。 特恵には制限はありません。 弊社のサイトで定期的にチェックしてクーポンを入手することができます。
あなたはDatabricks-Certified-Data-Engineer-Associate試験参考書の更新をどのぐらいでリリースしていますか?
すべての試験参考書は常に更新されますが、固定日付には更新されません。弊社の専門チームは、試験のアップデートに十分の注意を払い、彼らは常にそれに応じてDatabricks-Certified-Data-Engineer-Associate試験内容をアップグレードします。
返金するポリシーはありますか? 失敗した場合、どうすれば返金できますか?
はい。弊社はあなたが我々の練習問題を使用して試験に合格しないと全額返金を保証します。返金プロセスは非常に簡単です:購入日から60日以内に不合格成績書を弊社に送っていいです。弊社は成績書を確認した後で、返金を行います。お金は7日以内に支払い口座に戻ります。
Databricks-Certified-Data-Engineer-Associateテストエンジンはどのシステムに適用しますか?
オンラインテストエンジンは、WEBブラウザをベースとしたソフトウェアなので、Windows / Mac / Android / iOSなどをサポートできます。どんな電設備でも使用でき、自己ペースで練習できます。オンラインテストエンジンはオフラインの練習をサポートしていますが、前提条件は初めてインターネットで実行することです。
ソフトテストエンジンは、Java環境で運行するWindowsシステムに適用して、複数のコンピュータにインストールすることができます。
PDF版は、Adobe ReaderやFoxit Reader、Google Docsなどの読書ツールに読むことができます。
Databricks Databricks-Certified-Data-Engineer-Associate 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
参照:https://www.databricks.com/learn/certification/data-engineer-associate
更新されたDatabricks-Certified-Data-Engineer-Associate試験参考書を得ることができ、取得方法?
はい、購入後に1年間の無料アップデートを享受できます。更新があれば、私たちのシステムは更新されたDatabricks-Certified-Data-Engineer-Associate試験参考書をあなたのメールボックスに自動的に送ります。
あなたのテストエンジンはどのように実行しますか?
あなたのPCにダウンロードしてインストールすると、Databricks Databricks-Certified-Data-Engineer-Associateテスト問題を練習し、'練習試験'と '仮想試験'2つの異なるオプションを使用してあなたの質問と回答を確認することができます。
仮想試験 - 時間制限付きに試験問題で自分自身をテストします。
練習試験 - 試験問題を1つ1つレビューし、正解をビューします。
Tech4Examはどんな試験参考書を提供していますか?
テストエンジン:Databricks-Certified-Data-Engineer-Associate試験試験エンジンは、あなた自身のデバイスにダウンロードして運行できます。インタラクティブでシミュレートされた環境でテストを行います。
PDF(テストエンジンのコピー):内容はテストエンジンと同じで、印刷をサポートしています。
購入後、どれくらいDatabricks-Certified-Data-Engineer-Associate試験参考書を入手できますか?
あなたは5-10分以内にDatabricks Databricks-Certified-Data-Engineer-Associate試験参考書を付くメールを受信します。そして即時ダウンロードして勉強します。購入後にDatabricks-Certified-Data-Engineer-Associate試験参考書を入手しないなら、すぐにメールでお問い合わせください。
Databricks Certified Data Engineer Associate 認定 Databricks-Certified-Data-Engineer-Associate 試験問題:
A data engineer converts an external table to a managed table. A structured streaming job that reads from this table continues running during the conversion. After the conversion completes, the streaming job stops processing new records. How should the data engineer resolve this?
- A. Restart the streaming job, so it picks up the new managed table location
- B. Delete the streaming checkpoint directory and let the job reprocess from the beginning
- C. Run REFRESH TABLE on the converted table to update the streaming checkpoint
- D. Grant the streaming job additional permissions on the new managed storage location
正解:A 🗳️
解説: (Tech4Exam メンバーにのみ表示されます)
Which of the following describes the storage organization of a Delta table?
- A. Delta tables are stored in a single file that contains only the data stored within the table.
- B. Delta tables store their data in a single file and all metadata in a collection of files in a separate location.
- C. Delta tables are stored in a single file that contains data, history, metadata, and other attributes.
- D. Delta tables are stored in a collection of files that contain data, history, metadata, and other attributes.
- E. Delta tables are stored in a collection of files that contain only the data stored within the table.
正解:D 🗳️
Which of the following describes a scenario in which a data team will want to utilize cluster pools?
- A. An automated report needs to be version-controlled across multiple collaborators.
- B. An automated report needs to be made reproducible.
- C. An automated report needs to be runnable by all stakeholders.
- D. An automated report needs to be tested to identify errors.
- E. An automated report needs to be refreshed as quickly as possible.
正解:E 🗳️
解説: (Tech4Exam メンバーにのみ表示されます)
A data engineer is processing ingested streaming tables and needs to filter out NULL values in the order_datetime column from the raw streaming table orders_raw and store the results in a new table orders_valid using DLT. Which code snippet should the data engineer use?
- A.
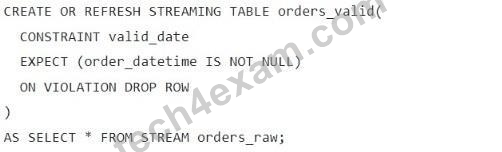
- B.
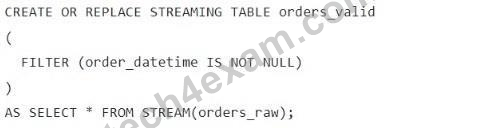
- C.
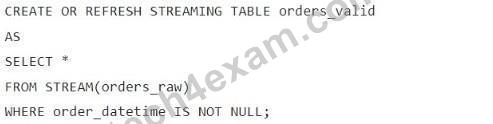
- D.
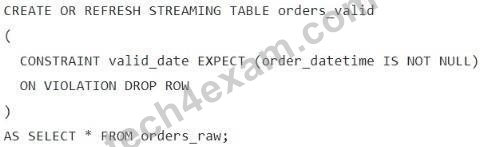
正解:A 🗳️
解説: (Tech4Exam メンバーにのみ表示されます)
A data engineer is using the following code block as part of a batch ingestion pipeline to read from a composable table: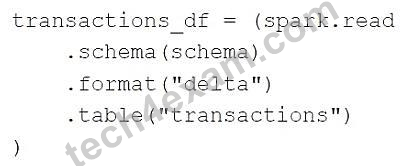
Which of the following changes needs to be made so this code block will work when the transactions table is a stream source?
- A. Replace spark.read with spark.readStream
- B. Replace predict with a stream-friendly prediction function
- C. Replace "transactions" with the path to the location of the Delta table
- D. Replace schema(schema) with option ("maxFilesPerTrigger", 1)
- E. Replace format("delta") with format("stream")
正解:A 🗳️
全 65 ページ中 1 ページ目を表示しています。
全 322 問中 1-5 問目を表示しています。

 -井*遥